

AI
Describes GLLmolfar 0.9.22current release 0.9.23 · checked 1 Nov 2026
What AI crawlers may fetch from the site and what they actually get, whether the pages read well for an assistant to quote, and which questions the site's passages answer. The bot check runs from this computer.
- Where
- AI › AI
- Mode
- Simple and Pro
- Built from
- The open crawl and a bot check of about 10 pages
- Changes
- When you press Check again or open another crawl
On the screen
At the top, the AI readiness score with its four parts. Below, two columns: on the left whether AI can get in and which questions the site answers; on the right whether AI can read and quote it, trust, llms.txt and Markdown for agents.
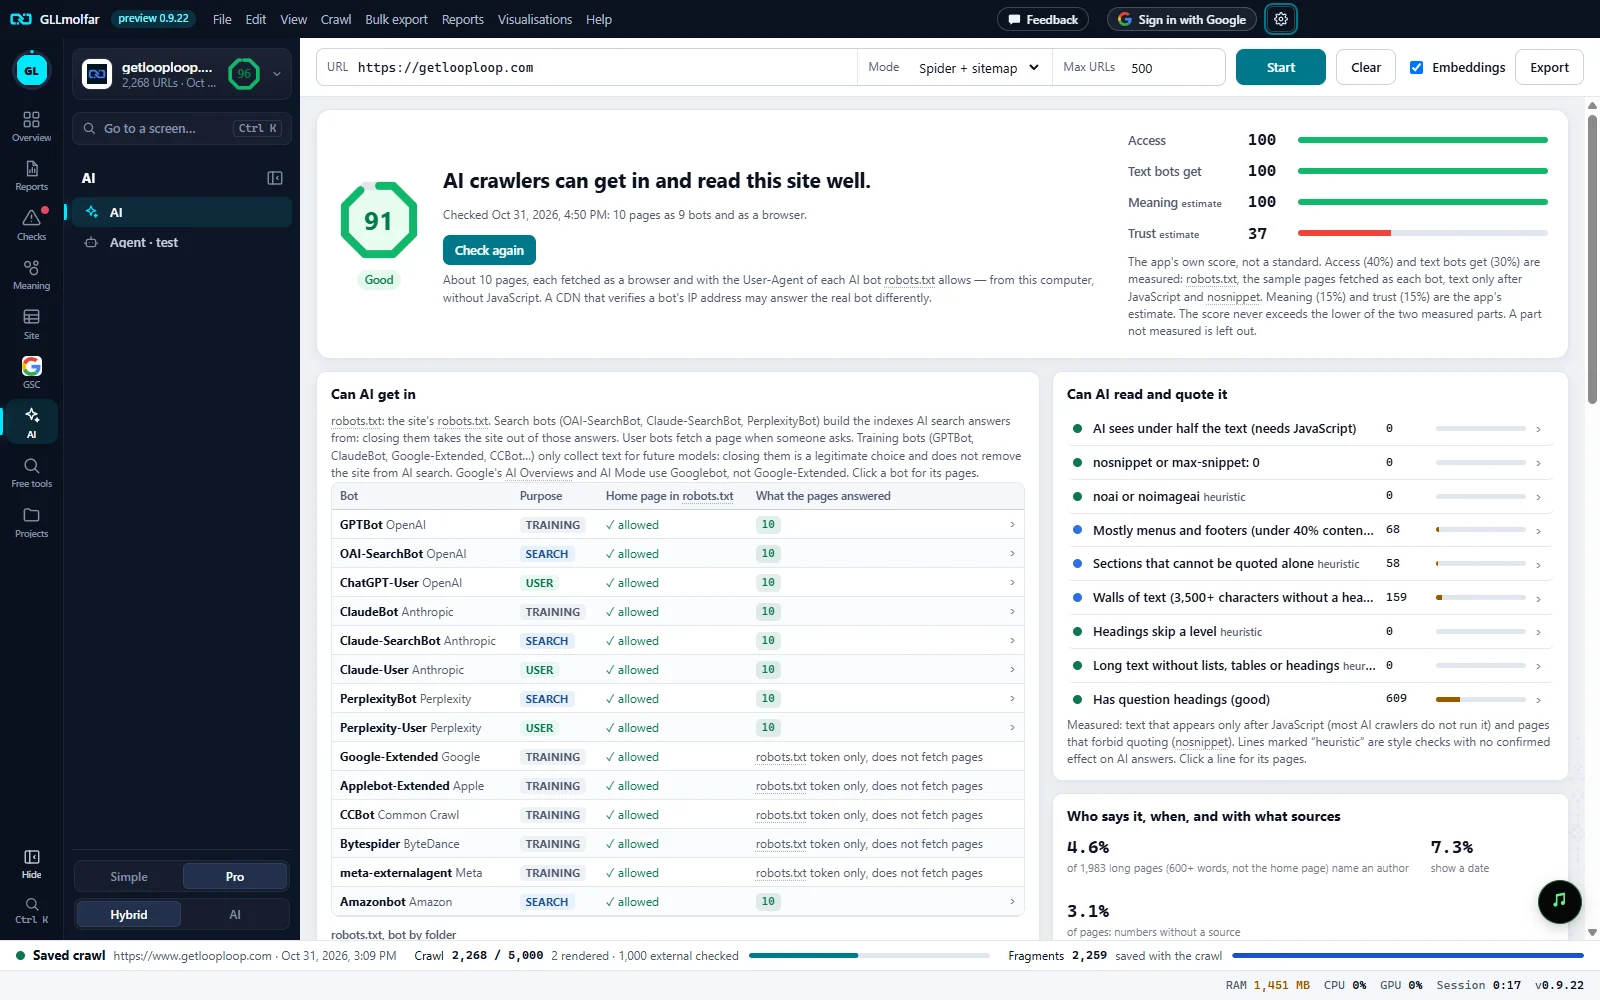
AI readiness. A score from 0 to 100 with its band.
Headline and check. One sentence about the site, when the bots were checked, and Check again. The note under it says how the check fetches.
Four parts. Access, Text bots get, Meaning and Trust, each with a bar. Meaning and Trust are marked estimate.
Can AI get in. Every AI bot with its purpose, whether robots.txt lets it into the home page, and what the sample pages answered. A bot opens its pages.
Can AI read and quote it. Lines with the number of pages each touches. Measured lines come first; style checks are marked heuristic. A line opens its pages.
What the pages answered. Pages fetched as that bot, by result. Bots that only exist as a robots.txt token say so.
Who says it. Authors, dates, unsourced numbers, the organization and its contacts across the site.
AI readiness
The app's own score, not a standard. Access (40%) and text bots get (30%) are measured: robots.txt, the sample pages fetched as each bot, text only after JavaScript and nosnippet. Meaning (15%) and trust (15%) are the app's estimate. The score never exceeds the lower of the two measured parts. A part not measured is left out and reads not checked yet.
| Score | Headline on screen |
|---|---|
| 80–100 | AI crawlers can get in and read this site well. |
| 55–79 | AI crawlers get in, but parts of the site are hard for them to read or quote. |
| 0–54 | AI crawlers are blocked or see little of this site. |
| Not checked | Check the site as AI bots to see how they get in. |
Can AI get in
Check as AI bots fetches about 10 pages, each as a browser and with the User-Agent of each AI bot robots.txt allows — from this computer, without JavaScript. A CDN that verifies a bot's IP address may answer the real bot differently.
| Column | What it shows |
|---|---|
| Bot | GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot, Claude-SearchBot, Claude-User, PerplexityBot, Perplexity-User, Google-Extended, Applebot-Extended, CCBot, Bytespider, meta-externalagent and Amazonbot, each with its owner. |
| Purpose | search bots build the indexes AI search answers from; user bots fetch a page when someone asks; training bots only collect text for future models. |
| Home page in robots.txt | allowed or blocked. A blocked training bot is grey and reads your choice, does not affect AI search. |
| What the pages answered | Counts by result: like a browser (60%+ of its text), under 60% of the browser's text, CAPTCHA or bot check, error or refused, blocked by robots.txt. |
A bot opens its pages: the address, what the page gave as a browser and as that bot (status and words), and the result. Under the table, robots.txt, bot by folder shows ✓ or ✕ for every bot in each folder; hovering gives the matching rule and its line.
Can AI read and quote it
| Line | Kind |
|---|---|
| AI sees under half the text (needs JavaScript) | Measured |
| nosnippet or max-snippet: 0 | Measured |
| noai or noimageai | heuristic |
| Mostly menus and footers (under 40% content) | heuristic |
| Sections that cannot be quoted alone | heuristic |
| Walls of text (3,500+ characters without a heading) | heuristic |
| Headings skip a level | heuristic |
| Long text without lists, tables or headings | heuristic |
| Has question headings (good) | A good sign, not a problem |
Lines marked “heuristic” are style checks with no confirmed effect on AI answers. They do not move the score.
The other blocks
| Block | What it shows |
|---|---|
| Which questions the site answers | Paste the questions people ask, one per line, and press Match questions. The local embedding model matches each with every section of the site: yes from similarity 0.56, weak from 0.42, with the best section and its page. Thresholds set on one site: a guide, not a verdict. |
| Questions people search | With Search Console connected: queries phrased as questions, with impressions, clicks and position, and a button to check them against the passages. |
| Who says it, when, and with what sources | The share of long pages (600+ words, not the home page) that name an author, the share that show a date, and the share of pages with numbers without a source. Then the organization, sameAs profiles, About and contact pages, phones and emails; pages state different values when they disagree. Four lines open their pages: no author, no date, not updated for over 18 months, numbers and claims without a source. |
| llms.txt | Whether llms.txt and llms-full.txt exist, their size, links and sections, links that lead to errors and links not in this crawl. When missing, a note on what the file is and that no major AI search engine has said it reads it. |
| Markdown for agents | For each sample page: whether it answers Accept: text/markdown with Markdown, and whether a .md version exists, with the words in each. A warning when Markdown is served without Vary: Accept. |
States and messages
Enter a site address above and press Start.
The tab needs a crawl.
AI bots have not been checked for this crawl.
Access, llms.txt and Markdown say Press Check as AI bots above.
Reading robots.txt…
A bar and the step: as a browser, as each bot, looking for llms.txt, asking for Markdown.
robots.txt did not answer (status N). Under RFC 9309 a crawler that cannot read robots.txt treats the whole site as closed, so AI bots may skip it entirely.
Access counts as zero.
Crawl again to read authors, dates and sources (crawls before 0.7.5 do not have them).
The trust block stays empty.