

Crawl diagnosis
Describes GLLmolfar 0.9.35current release · checked 8 Nov 2026
A crawl with fewer pages than expected has a reason: robots.txt closed paths, the site asked to slow down, pages did not answer, a bot check stood in the way, or the scope left URLs out. Molfar shows the rules and the pace while the crawl runs, and afterwards lists what shaped it.
- Where
- The crawl's overview while it runs; Crawl › Diagnosis…, or the button on the robots.txt line
- Mode
- Simple and Pro
- Built from
- The crawl's pages and its own notes; nothing is fetched again
- Changes
- During the crawl; the diagnosis when it is opened
While the crawl runs
Under the crawl's progress, one line says who is crawling and one says the rules it runs under. The part of the first line that names this computer's address is hidden in this picture.
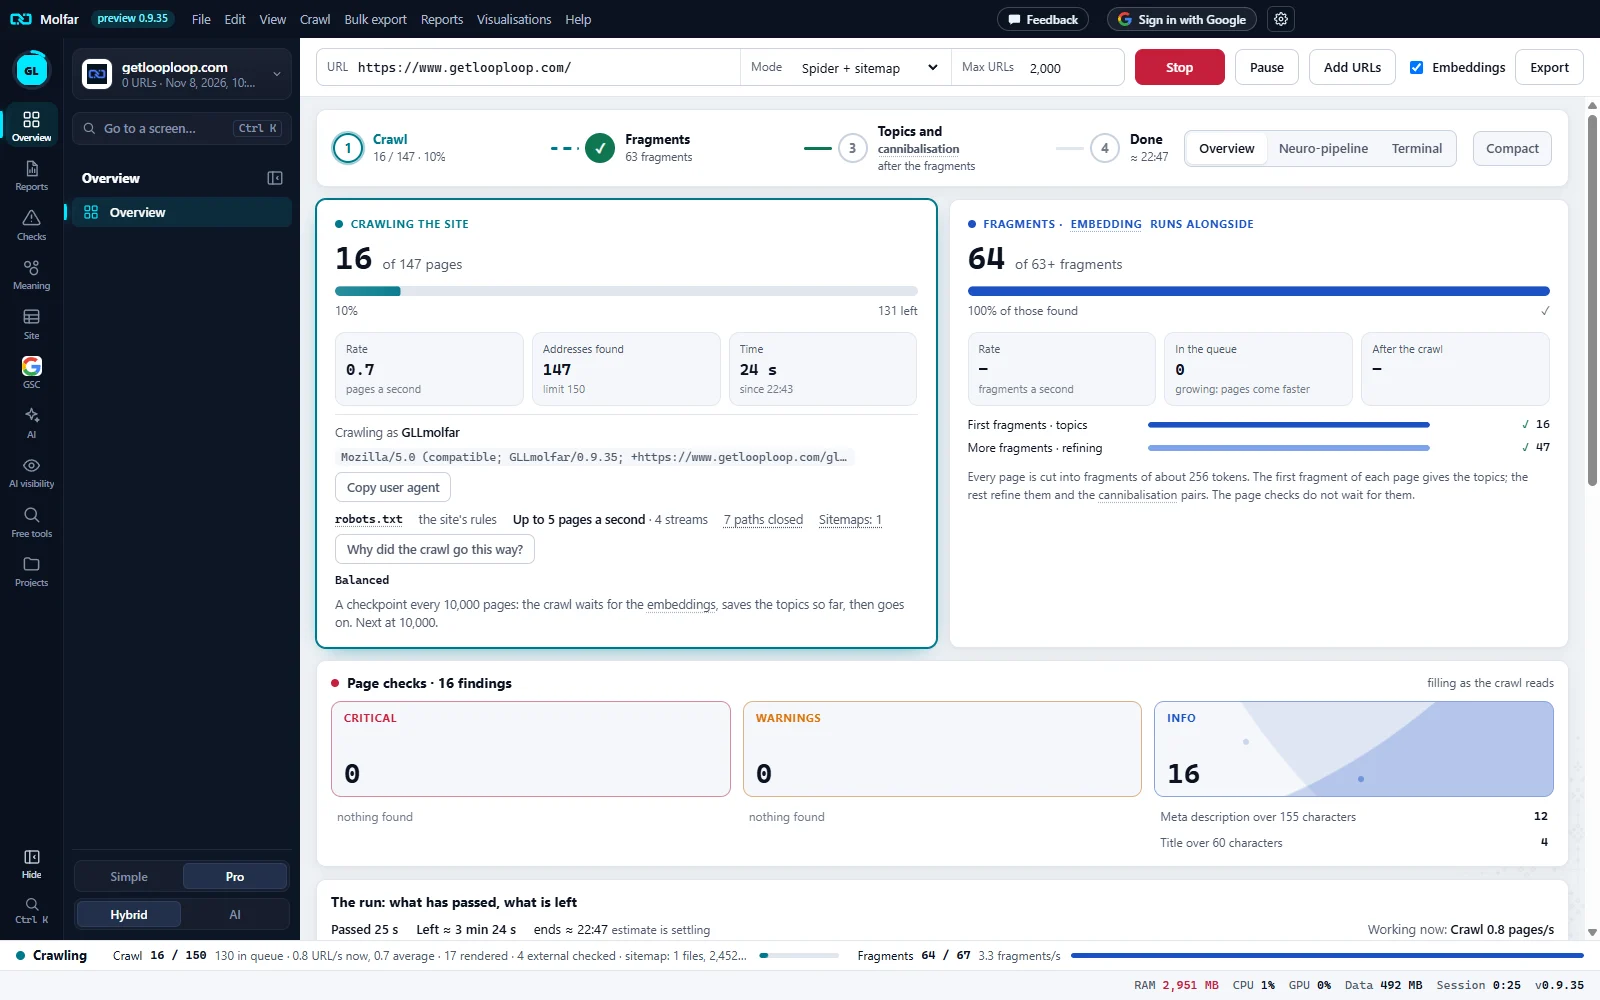
Crawling as. The user agent the site sees, with Copy user agent to search the site's logs for it. The app also says from which address; that part is hidden here.
robots.txt. Whose rules: the site's rules here; also your own rules (Settings) or the site has none: no limits.
Pace. Up to 5 pages a second · 4 streams here; One page every N s when robots.txt sets a Crawl-delay, which is kept and named.
Closed paths, sitemaps, AI bots. 7 paths closed and Sitemaps: 1 here (hover for the list); Closed to AI bots: and which, when robots.txt shuts them out.
Why did the crawl go this way?. Opens the Diagnosis panel.
| The line says | What happened |
|---|---|
| The site answered {code}: slowed to {n} of {max} streams | A 429 or 503: Molfar halves its parallel requests to that site. |
| The site stopped answering: paused for {s} s, then one stream | Connections dropped: a pause, then one request at a time. |
| After dropped connections: {n} of {max} streams | Still slower after the pause. |
| Speeding back up: {n} of {max} streams | The site answers again; the pace returns step by step. |
| The site slowed the crawl {n} times | After the slow-down, how often it happened. |
429, 502, 503 and 504 answers and network failures are asked again with growing pauses; a 404, 403 or 500 is recorded once, as the page's state.
The Diagnosis panel
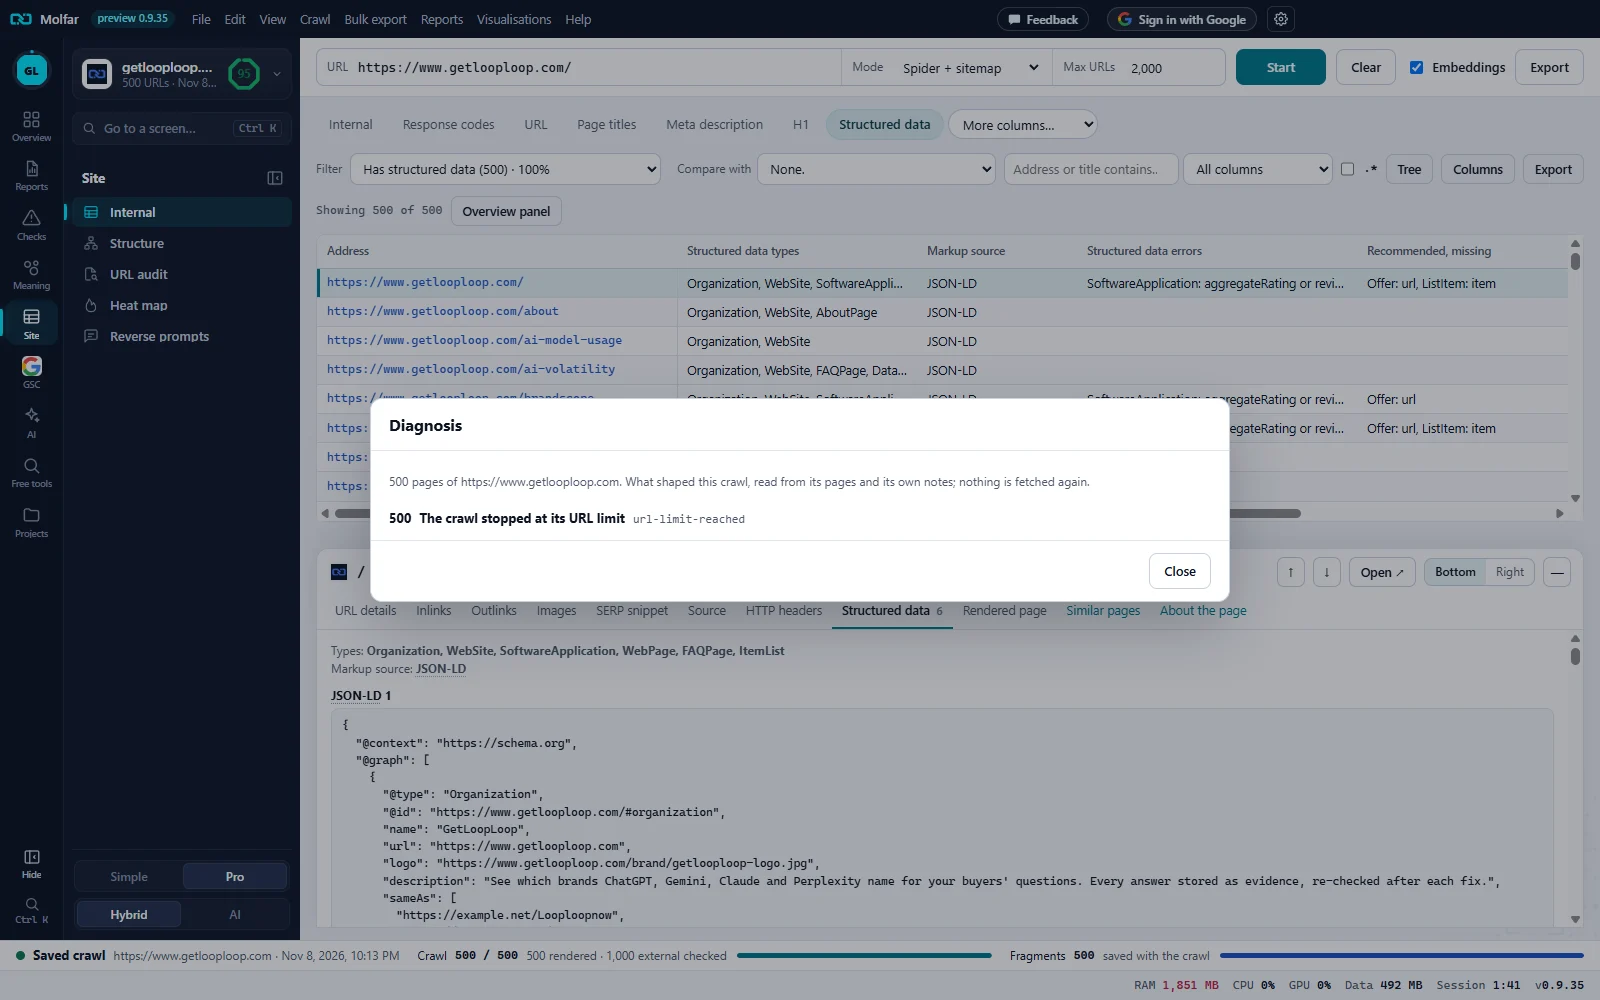
What was read. How many pages, of which site. It is read from the crawl's pages and its own notes; nothing is fetched again.
A finding. Its count, a sentence, and the code an agent reads: here 500 · The crawl stopped at its URL limit · url-limit-reached. Other findings list up to five examples under them.
Close. The panel only reads; closing it changes nothing.
| Code | The panel says |
|---|---|
robots-disallow | robots.txt rules close paths to this crawler |
robots-ai-blocked | robots.txt closes the site to AI bots |
robots-crawl-delay | robots.txt asks for a pause between requests (Crawl-delay); the crawl kept to it |
no-response | Pages that did not answer (with how many timed out) |
http-429 | Pages answered 429 Too Many Requests: the site asked the crawl to slow down |
http-503 | Pages answered 503 Service Unavailable |
bot-check | Pages answered with a CAPTCHA or a bot check instead of content (with which checks) |
site-slowed-crawl | Times the site's answers slowed the crawl down or paused it |
excluded-by-scope | URLs left out by the crawl scope (include, exclude, parameters, start folder, URLs per host) |
languages-left-out | URLs in the site's other languages left out (Main language only) |
url-limit-reached | The crawl stopped at its URL limit |
States and messages
Open or run a crawl first: the diagnosis reads its pages.
The menu item is off until a crawl has pages.
Nothing held this crawl back: {n} pages, no robots.txt rules, refusals, bot checks, slow-downs, scope exclusions or URL limit.
No finding applies.
reading the site's robots.txt…
The first moments of a crawl, before the rules are known.